Charts
Track A: AbsRel, raw metric output vs per-image median scaling
Track A: AbsRel per camera (raw metric output)
Track A: AbsRel per camera (median-scaled = shape error)
Track A: AbsRel per depth bin (raw / scaled)
Track A: median scale factor GT/pred per camera (1.0 = metric scale correct)
Track C: held-out PSNR (higher is better)
Track C: held-out SSIM (higher is better)
Track C: held-out LPIPS alex (lower is better)
Track C: training loss and number of Gaussians
Track B: AbsRel on identical reference pixels, mean with 95% bootstrap CI
Track B: VGGT relative pose errors vs nuScenes GT (per view pair)
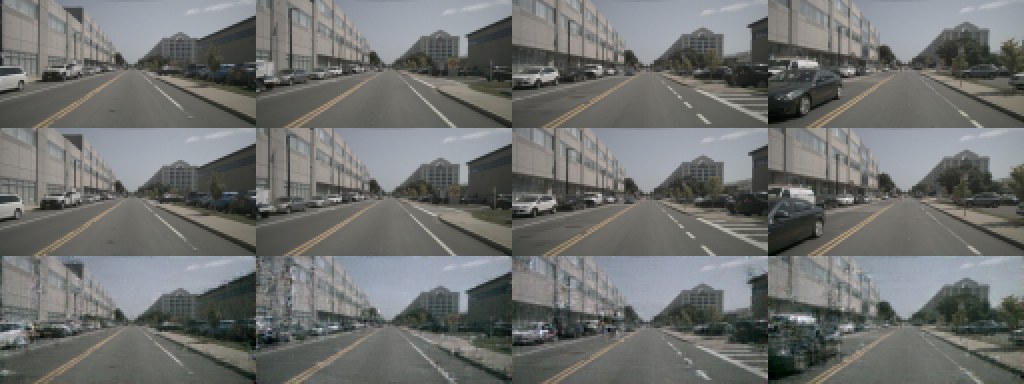
Track E: PSNR vs real next frame, 95% CI over held-out pairs
Track E: LPIPS (alex) vs real next frame, 95% CI over held-out pairs
Track E: training loss
Track D: SHARP render vs real frame, PSNR and LPIPS
Depth comparison viewer

Colour scale: log depth 1-80 m (turbo, red = near). AbsRel on this frame's LiDAR pixels is shown on the right.
3D point cloud: VGGT vs LiDAR
VGGT point map of CAM_FRONT in scene-0061 (114,040 points, coloured by the image, scaled to LiDAR with one sequence scale) and the LiDAR return of the same keyframe (11,609 points, white). Drag to orbit, wheel to zoom. Toggle:
Trained 3D Gaussian Splatting scene
491,520 of 736,227 Gaussians from the 'lidar_depth0.2' variant (15.7 MB .splat). Drag to orbit, right-drag to pan, wheel to zoom. Moving cars and pedestrians appear as ghosts because the scene is modelled as static.
Renders
3DGS held-out previews
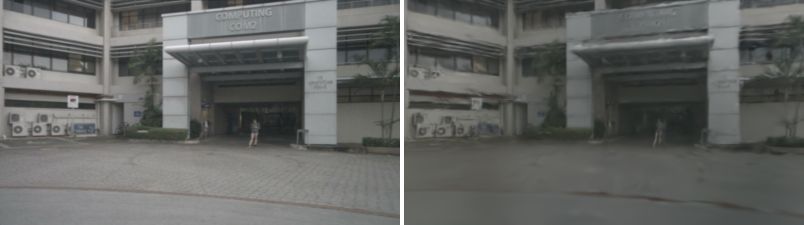
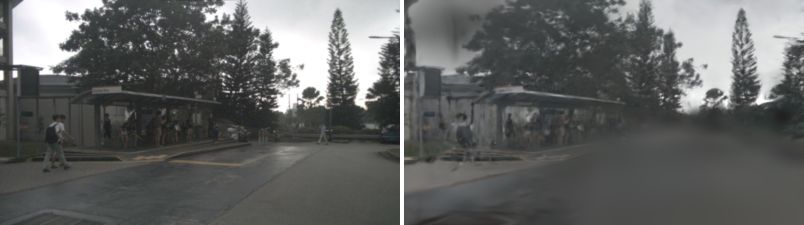
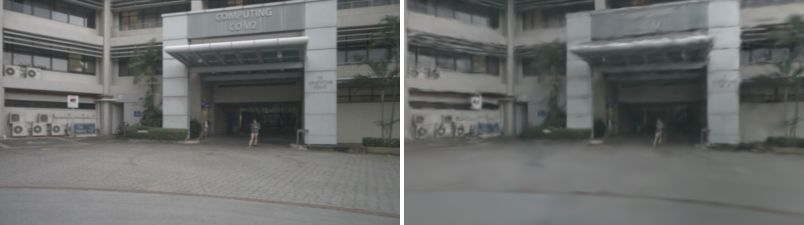
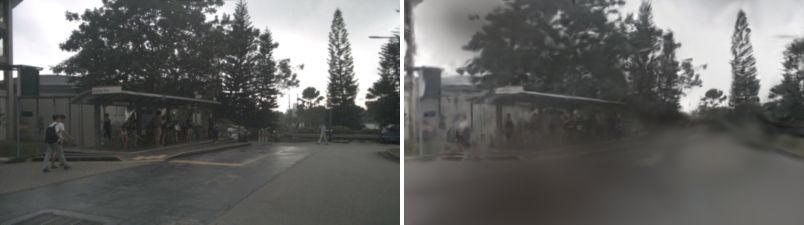
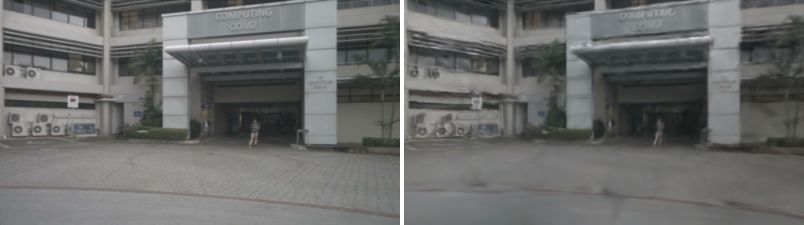
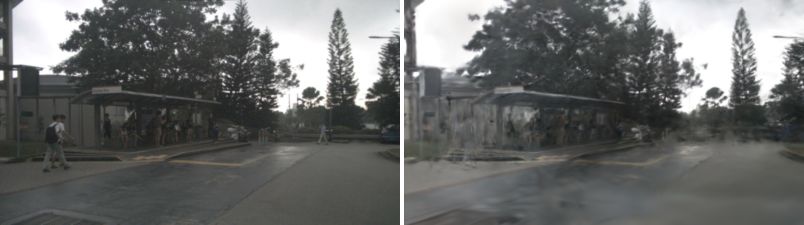
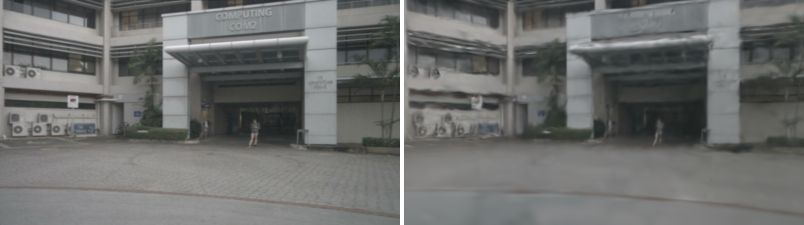
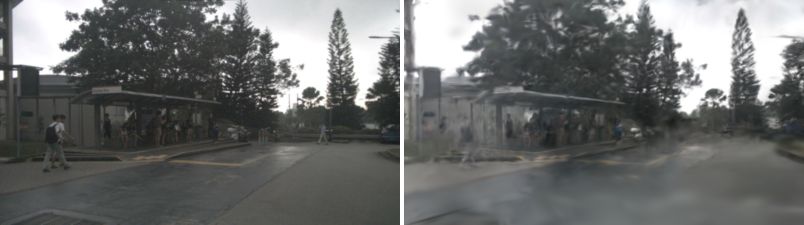
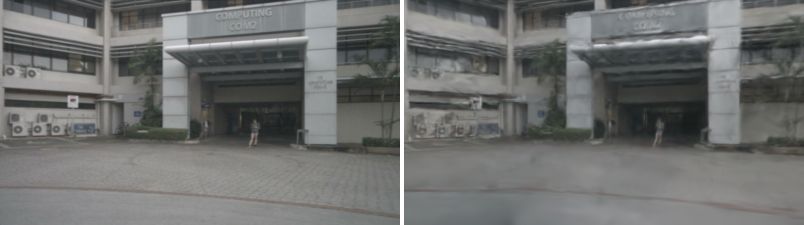
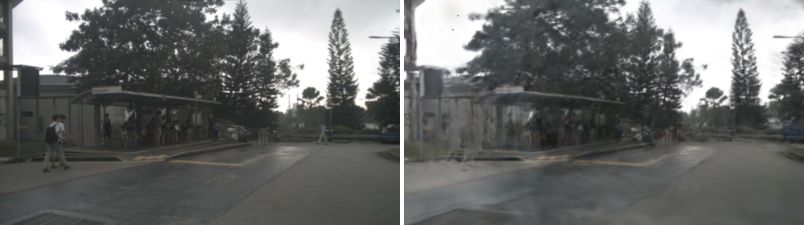
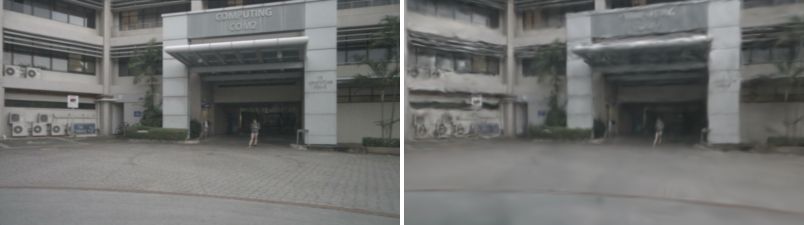
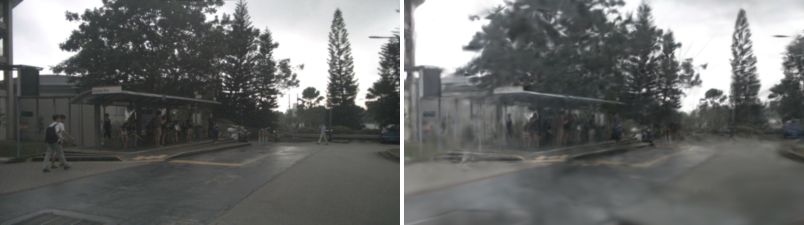
3DGS camera path
Track E: real vs generated next frames
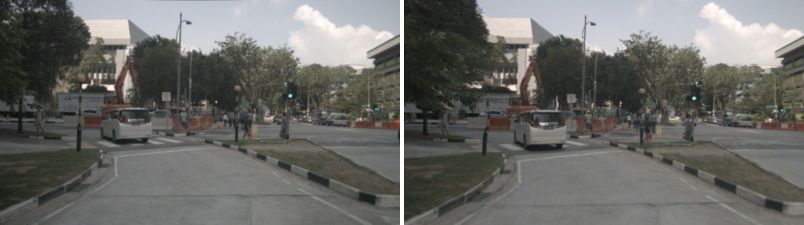
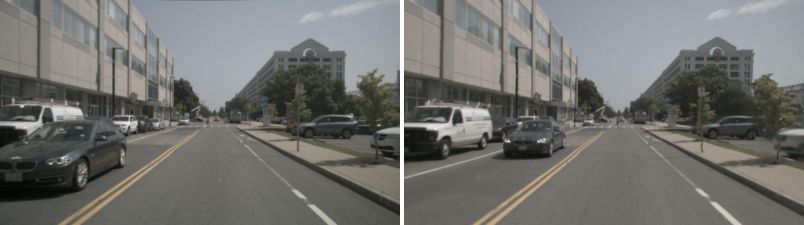
Track D: SHARP renders
All result tables (docs/RESULTS.md)
Results
Generated by python scripts/make_results.py from results/*.json. Do not edit by hand. All timings measured on an NVIDIA L4 (23 GB). Dataset: nuScenes v1.0-mini (10 scenes, 404 keyframes).
Track A - monocular metric depth vs LiDAR (zero-shot)
LiDAR ground truth: 2,424 images (404 keyframes x 6 cameras), points with 1 m < z < 80 m after z-buffering. Per camera (points per image, median depth):
| camera | pts/img | median z [m] | frac 1-20 m | frac 20-40 m | frac 40-80 m |
|---|---|---|---|---|---|
| CAM_FRONT | 3020 | 11.9 | 0.69 | 0.23 | 0.09 |
| CAM_FRONT_LEFT | 3344 | 9.2 | 0.85 | 0.13 | 0.03 |
| CAM_FRONT_RIGHT | 3189 | 10.7 | 0.70 | 0.22 | 0.09 |
| CAM_BACK | 4521 | 9.8 | 0.74 | 0.19 | 0.07 |
| CAM_BACK_LEFT | 4000 | 8.4 | 0.87 | 0.12 | 0.01 |
| CAM_BACK_RIGHT | 3614 | 10.8 | 0.70 | 0.23 | 0.07 |
Overall (all LiDAR points, all cameras)
| variant | AbsRel | SqRel | RMSE [m] | RMSE_log | d<1.25 | d<1.25^2 | d<1.25^3 | images | ms/img (NVIDIA L4) |
|---|---|---|---|---|---|---|---|---|---|
| depth_pro raw | 0.257 | 2.123 | 7.760 | 0.488 | 0.525 | 0.800 | 0.894 | 2,424 | 599 |
| depth_pro median-scaled | 0.178 | 1.629 | 6.725 | 0.314 | 0.760 | 0.902 | 0.951 | 2,424 | |
| depth_pro_gtfocal raw | 0.277 | 2.448 | 8.579 | 0.553 | 0.460 | 0.727 | 0.858 | 2,424 | 599 |
| depth_pro_gtfocal median-scaled | 0.178 | 1.629 | 6.725 | 0.314 | 0.760 | 0.902 | 0.951 | 2,424 | |
| dav2_metric_outdoor_large raw | 0.582 | 5.133 | 8.957 | 0.524 | 0.199 | 0.604 | 0.787 | 2,424 | 365 |
| dav2_metric_outdoor_large median-scaled | 0.194 | 1.643 | 7.446 | 0.336 | 0.715 | 0.871 | 0.937 | 2,424 |
'raw' is the metric output as predicted; 'median-scaled' multiplies each image by median(GT)/median(pred) so that the remaining error is shape error only. 'depth_pro_gtfocal' feeds the true nuScenes focal length instead of the model's own focal estimate. Timing is the median model time per 1600x900 image.
Scale factor and focal estimate per camera
| variant | camera | median scale GT/pred | p10 / p90 | true f [px] | pred f median [px] | pred/true f |
|---|---|---|---|---|---|---|
| depth_pro | CAM_FRONT | 1.122 | 0.881 / 1.467 | 1266 | 1324 | 1.046 |
| depth_pro | CAM_FRONT_LEFT | 1.298 | 1.018 / 1.967 | 1273 | 1322 | 1.039 |
| depth_pro | CAM_FRONT_RIGHT | 1.212 | 0.988 / 1.697 | 1261 | 1377 | 1.092 |
| depth_pro | CAM_BACK | 0.943 | 0.767 / 1.266 | 809 | 1033 | 1.276 |
| depth_pro | CAM_BACK_LEFT | 1.195 | 0.930 / 2.508 | 1257 | 1366 | 1.087 |
| depth_pro | CAM_BACK_RIGHT | 1.249 | 1.024 / 1.641 | 1260 | 1415 | 1.123 |
| depth_pro_gtfocal | CAM_FRONT | 1.165 | 0.951 / 1.529 | 1266 | 1324 | 1.046 |
| depth_pro_gtfocal | CAM_FRONT_LEFT | 1.342 | 1.072 / 2.176 | 1273 | 1322 | 1.039 |
| depth_pro_gtfocal | CAM_FRONT_RIGHT | 1.287 | 1.073 / 2.012 | 1261 | 1377 | 1.092 |
| depth_pro_gtfocal | CAM_BACK | 1.169 | 1.008 / 1.570 | 809 | 1033 | 1.276 |
| depth_pro_gtfocal | CAM_BACK_LEFT | 1.267 | 1.063 / 3.170 | 1257 | 1366 | 1.087 |
| depth_pro_gtfocal | CAM_BACK_RIGHT | 1.390 | 1.076 / 2.069 | 1260 | 1415 | 1.123 |
| dav2_metric_outdoor_large | CAM_FRONT | 0.728 | 0.625 / 0.847 | n/a | n/a | n/a |
| dav2_metric_outdoor_large | CAM_FRONT_LEFT | 0.685 | 0.571 / 0.971 | n/a | n/a | n/a |
| dav2_metric_outdoor_large | CAM_FRONT_RIGHT | 0.757 | 0.628 / 0.918 | n/a | n/a | n/a |
| dav2_metric_outdoor_large | CAM_BACK | 0.474 | 0.432 / 0.557 | n/a | n/a | n/a |
| dav2_metric_outdoor_large | CAM_BACK_LEFT | 0.677 | 0.522 / 0.961 | n/a | n/a | n/a |
| dav2_metric_outdoor_large | CAM_BACK_RIGHT | 0.765 | 0.612 / 0.934 | n/a | n/a | n/a |
A scale factor of 1.0 means the metric output is already on the LiDAR scale for that camera.
Per camera group (front / side / back) - AbsRel and d<1.25
| variant | group | AbsRel raw | AbsRel scaled | d1 raw | d1 scaled | points |
|---|---|---|---|---|---|---|
| depth_pro | front | 0.191 | 0.124 | 0.633 | 0.845 | 1,219,883 |
| depth_pro | side | 0.270 | 0.190 | 0.495 | 0.739 | 5,715,488 |
| depth_pro | back | 0.259 | 0.177 | 0.549 | 0.771 | 1,826,681 |
| depth_pro_gtfocal | front | 0.202 | 0.124 | 0.595 | 0.845 | 1,219,883 |
| depth_pro_gtfocal | side | 0.306 | 0.190 | 0.411 | 0.739 | 5,715,488 |
| depth_pro_gtfocal | back | 0.236 | 0.177 | 0.525 | 0.771 | 1,826,681 |
| dav2_metric_outdoor_large | front | 0.399 | 0.140 | 0.242 | 0.821 | 1,219,883 |
| dav2_metric_outdoor_large | side | 0.477 | 0.207 | 0.222 | 0.697 | 5,715,488 |
| dav2_metric_outdoor_large | back | 1.034 | 0.191 | 0.097 | 0.699 | 1,826,681 |
Per camera - AbsRel raw / scaled
| variant | CAM_FRONT | CAM_FRONT_LEFT | CAM_FRONT_RIGHT | CAM_BACK | CAM_BACK_LEFT | CAM_BACK_RIGHT |
|---|---|---|---|---|---|---|
| depth_pro | 0.191 / 0.124 | 0.286 / 0.182 | 0.237 / 0.204 | 0.259 / 0.177 | 0.301 / 0.174 | 0.251 / 0.202 |
| depth_pro_gtfocal | 0.202 / 0.124 | 0.310 / 0.182 | 0.275 / 0.204 | 0.236 / 0.177 | 0.326 / 0.174 | 0.309 / 0.202 |
| dav2_metric_outdoor_large | 0.399 / 0.140 | 0.514 / 0.202 | 0.432 / 0.215 | 1.034 / 0.191 | 0.542 / 0.190 | 0.412 / 0.223 |
Per depth bin - AbsRel and RMSE
| variant | bin | AbsRel raw | AbsRel scaled | RMSE raw [m] | RMSE scaled [m] | points |
|---|---|---|---|---|---|---|
| depth_pro | 1-20m | 0.242 | 0.158 | 3.52 | 2.99 | 6,653,105 |
| depth_pro | 20-40m | 0.280 | 0.216 | 10.22 | 8.81 | 1,599,744 |
| depth_pro | 40-80m | 0.373 | 0.315 | 23.38 | 20.43 | 509,203 |
| depth_pro_gtfocal | 1-20m | 0.250 | 0.158 | 3.58 | 2.99 | 6,653,105 |
| depth_pro_gtfocal | 20-40m | 0.338 | 0.216 | 11.55 | 8.81 | 1,599,744 |
| depth_pro_gtfocal | 40-80m | 0.438 | 0.315 | 26.08 | 20.43 | 509,203 |
| dav2_metric_outdoor_large | 1-20m | 0.668 | 0.168 | 6.96 | 2.50 | 6,653,105 |
| dav2_metric_outdoor_large | 20-40m | 0.334 | 0.238 | 12.10 | 9.21 | 1,599,744 |
| dav2_metric_outdoor_large | 40-80m | 0.250 | 0.405 | 16.98 | 24.62 | 509,203 |
Reading the scale error (generated from the tables above)
depth_pro: per-image median scaling lowers AbsRel from 0.257 to 0.178, i.e. 31% of the raw error is a per-image scale error and the rest is shape error. Worst camera group raw: side (AbsRel 0.270), best: front (0.191). Median scale factor CAM_FRONT 1.12 vs CAM_BACK 0.94. Focal estimate / true focal: CAM_FRONT 1.05, CAM_BACK 1.28. Fraction of LiDAR pixels where the raw prediction exceeded 80 m (clipped before scoring): 0.08%.
depth_pro_gtfocal: per-image median scaling lowers AbsRel from 0.277 to 0.178, i.e. 36% of the raw error is a per-image scale error and the rest is shape error. Worst camera group raw: side (AbsRel 0.306), best: front (0.202). Median scale factor CAM_FRONT 1.16 vs CAM_BACK 1.17. Focal estimate / true focal: CAM_FRONT 1.05, CAM_BACK 1.28. Fraction of LiDAR pixels where the raw prediction exceeded 80 m (clipped before scoring): 0.06%.
dav2_metric_outdoor_large: per-image median scaling lowers AbsRel from 0.582 to 0.194, i.e. 67% of the raw error is a per-image scale error and the rest is shape error. Worst camera group raw: back (AbsRel 1.034), best: front (0.399). Median scale factor CAM_FRONT 0.73 vs CAM_BACK 0.47. Fraction of LiDAR pixels where the raw prediction exceeded 80 m (clipped before scoring): 0.00%.
Per-image AbsRel, mean with 95% bootstrap CI over images
| variant | raw | median-scaled |
|---|---|---|
| depth_pro | 0.255 [0.250, 0.260] | 0.177 [0.173, 0.182] |
| depth_pro_gtfocal | 0.276 [0.271, 0.282] | 0.177 [0.173, 0.182] |
| dav2_metric_outdoor_large | 0.560 [0.549, 0.571] | 0.193 [0.189, 0.197] |
Track C - 3D Gaussian Splatting on one driving scene (gsplat, own training loop)
Scene choice: moving annotations (box velocity > 0.5 m/s) per scene; selected scene-0916.
| scene | keyframes | annotations | moving (velocity) | frac moving | moving (attribute) |
|---|---|---|---|---|---|
| scene-0916 | 41 | 2,424 | 186 | 0.08 | 265 |
| scene-0655 | 41 | 2,373 | 213 | 0.09 | 216 |
| scene-0757 | 41 | 604 | 294 | 0.49 | 297 |
| scene-1100 | 40 | 956 | 492 | 0.51 | 611 |
| scene-0796 | 40 | 716 | 588 | 0.82 | 599 |
| scene-1077 | 41 | 909 | 701 | 0.77 | 762 |
| scene-0553 | 41 | 1,991 | 796 | 0.40 | 778 |
| scene-0103 | 40 | 2,090 | 968 | 0.46 | 1,058 |
| scene-0061 | 39 | 4,699 | 1,017 | 0.22 | 1,114 |
| scene-1094 | 40 | 1,776 | 1,191 | 0.67 | 1,195 |
Scene scene-0916, 216 train / 30 held-out views (every 8th timestamp (offset 4), all 6 cameras), images 800x450 (downscale 2), 7000 steps, seed 0, NVIDIA L4.
| variant | depth w | PSNR test | SSIM | LPIPS (alex) | init gaussians | final gaussians | train min (NVIDIA L4) | render ms/view | PSNR train subset |
|---|---|---|---|---|---|---|---|---|---|
| random | - | 13.40 +- 3.78 | 0.521 | 0.758 | 200,000 | 206,811 | 1.5 | 1.9 | 20.01 |
| lidar | - | 16.29 +- 2.75 | 0.587 | 0.580 | 300,000 | 576,114 | 2.9 | 3.5 | 21.24 |
| lidar_depth0.05 | 0.05 | 17.54 +- 2.66 | 0.599 | 0.525 | 300,000 | 674,323 | 3.3 | 3.9 | 21.66 |
| lidar_depth0.2 | 0.20 | 18.51 +- 2.77 | 0.608 | 0.497 | 300,000 | 736,227 | 3.5 | 4.2 | 21.48 |
| random_15k | - | 12.36 +- 2.45 | 0.512 | 0.729 | 200,000 | 427,153 | 4.4 | 2.6 | 20.61 |
| lidar_15k | - | 14.04 +- 3.42 | 0.522 | 0.605 | 300,000 | 948,796 | 8.4 | 5.0 | 22.44 |
| lidar_depth0.05_15k | 0.05 | 16.94 +- 2.79 | 0.574 | 0.469 | 300,000 | 1,337,190 | 11.6 | 7.2 | 23.43 |
| lidar_depth0.2_15k | 0.20 | 18.32 +- 2.63 | 0.584 | 0.417 | 300,000 | 1,516,755 | 12.8 | 8.3 | 23.32 |
LiDAR init vs random init: 2.89 dB PSNR on held-out views (positive favours LiDAR init).
lidar_depth0.05 vs lidar: 1.26 dB PSNR, -0.054 LPIPS (negative LPIPS favours depth supervision).
lidar_depth0.2 vs lidar: 2.22 dB PSNR, -0.083 LPIPS (negative LPIPS favours depth supervision).
Held-out PSNR per camera
| variant | CAM_BACK | CAM_BACK_LEFT | CAM_BACK_RIGHT | CAM_FRONT | CAM_FRONT_LEFT | CAM_FRONT_RIGHT |
|---|---|---|---|---|---|---|
| random | 16.05 | 13.15 | 13.06 | 13.03 | 12.57 | 12.51 |
| lidar | 18.08 | 14.74 | 16.77 | 17.44 | 14.23 | 16.46 |
| lidar_depth0.05 | 18.83 | 16.06 | 17.35 | 18.18 | 16.95 | 17.89 |
| lidar_depth0.2 | 20.54 | 17.17 | 18.49 | 18.68 | 17.89 | 18.28 |
| random_15k | 12.66 | 12.55 | 12.91 | 12.29 | 11.85 | 11.92 |
| lidar_15k | 17.18 | 12.28 | 15.74 | 13.82 | 11.22 | 14.02 |
| lidar_depth0.05_15k | 18.52 | 15.36 | 17.34 | 17.89 | 15.31 | 17.24 |
| lidar_depth0.2_15k | 20.54 | 16.72 | 17.99 | 19.04 | 17.37 | 18.27 |
Track B - feed-forward multi-view reconstruction (VGGT) vs LiDAR
Model: VGGT-1B (facebook/VGGT-1B), bf16 autocast, input 518x294. Mono reference: Depth Pro on the same reference image and LiDAR pixels. GPU: NVIDIA L4.
Setting (i) 6-camera rig, one timestamp, reference CAM_FRONT
40 sequences, 120,040 LiDAR points on the reference views, 1333 ms per sequence (NVIDIA L4, incl. Depth Pro and metrics).
| alignment / model | AbsRel mean [95% CI] | d<1.25 | RMSE [m] |
|---|---|---|---|
| vggt_raw | 0.901 [0.898, 0.903] | ||
| vggt_seq_scaled | 0.135 [0.120, 0.149] | 0.818 [0.787, 0.848] | 6.80 [6.08, 7.57] |
| vggt_sim3_scaled | 0.607 [0.517, 0.699] | ||
| vggt_img_scaled | 0.124 [0.108, 0.140] | 0.854 [0.828, 0.880] | 6.35 [5.64, 7.10] |
| depth_pro_raw | 0.188 [0.166, 0.211] | ||
| depth_pro_img_scaled | 0.135 [0.116, 0.161] | 0.821 [0.767, 0.863] | 6.74 [6.12, 7.36] |
| depth_pro_gtfocal_raw | 0.200 [0.178, 0.223] |
Paired difference on identical pixels, VGGT (one scale per sequence) minus Depth Pro (per-image scale): -0.001 [-0.024, 0.017]; VGGT with per-image scale minus Depth Pro: -0.012 [-0.029, 0.003]. Negative means VGGT is better. Fraction of sequences where VGGT (seq scale) is lower: 0.42.
Relative camera pose vs nuScenes GT over 200 view pairs: rotation error mean 8.12 deg (median 4.65), translation direction error mean 48.6 deg (median 35.9, over the 200 pairs whose GT baseline exceeds 0.1 m; 0 pairs with a stationary ego vehicle have no defined direction and are excluded); mean GT baseline 0.81 m. Median sequence scale factor (LiDAR / VGGT units): 23.42.
Setting (ii) 5 consecutive CAM_FRONT keyframes, reference = centre frame
40 sequences, 120,495 LiDAR points on the reference views, 1192 ms per sequence (NVIDIA L4, incl. Depth Pro and metrics).
| alignment / model | AbsRel mean [95% CI] | d<1.25 | RMSE [m] |
|---|---|---|---|
| vggt_raw | 0.901 [0.898, 0.904] | ||
| vggt_seq_scaled | 0.118 [0.097, 0.146] | 0.867 [0.818, 0.903] | 5.88 [5.18, 6.68] |
| vggt_sim3_scaled | 0.321 [0.208, 0.452] | ||
| vggt_img_scaled | 0.123 [0.100, 0.153] | 0.862 [0.808, 0.902] | 5.93 [5.19, 6.74] |
| depth_pro_raw | 0.186 [0.162, 0.211] | ||
| depth_pro_img_scaled | 0.128 [0.112, 0.151] | 0.831 [0.778, 0.872] | 6.45 [5.88, 7.07] |
| depth_pro_gtfocal_raw | 0.191 [0.170, 0.214] |
Paired difference on identical pixels, VGGT (one scale per sequence) minus Depth Pro (per-image scale): -0.010 [-0.026, 0.007]; VGGT with per-image scale minus Depth Pro: -0.005 [-0.020, 0.012]. Negative means VGGT is better. Fraction of sequences where VGGT (seq scale) is lower: 0.70.
Relative camera pose vs nuScenes GT over 160 view pairs: rotation error mean 0.31 deg (median 0.14), translation direction error mean 2.3 deg (median 2.0, over the 120 pairs whose GT baseline exceeds 0.1 m; 40 pairs with a stationary ego vehicle have no defined direction and are excluded); mean GT baseline 4.24 m. Median sequence scale factor (LiDAR / VGGT units): 29.68.
Track E - next-frame synthesis with conditional flow matching (plain PyTorch)
Data: 2,342 CAM_FRONT frames (keyframes + sweeps, 404 keyframes) at 128x64; 1,865 train / 467 test consecutive pairs (median dt 0.10 s); held-out scenes scene-0655, scene-1094.
Training fm: 12.4M-parameter UNet, 2,150 steps, batch 64, lr 0.0002, 40.0 min on NVIDIA L4 (world size 1; the two trainings shared the GPU), final logged loss 0.0430.
Training regression: 12.4M-parameter UNet, 2,150 steps, batch 64, lr 0.0002, 40.0 min on NVIDIA L4 (world size 1; the two trainings shared the GPU), final logged loss 0.0025.
Evaluation on 467 held-out pairs, sampler Euler, 50 steps, 173.8 ms per sampled frame (NVIDIA L4).
| method | PSNR vs real next frame [95% CI] | LPIPS (alex) [95% CI] |
|---|---|---|
| fm_sample | 23.82 [23.61, 24.04] | 0.099 [0.096, 0.102] |
| regression | 24.74 [24.52, 24.98] | 0.121 [0.119, 0.123] |
| copy_current | 24.38 [24.09, 24.69] | 0.040 [0.038, 0.042] |
Paired LPIPS, flow-matching sample minus regression UNet: -0.022 [-0.025, -0.019] (negative = sample is perceptually closer).
Paired LPIPS, sample minus copy-current-frame: 0.059 [0.057, 0.061]; paired PSNR: -0.56 [-0.73, -0.40] dB.
FID of unconditional samples vs held-out frames: 390.3 (467 generated, 467 real). unconditional samples (condition zeroed) vs held-out real frames, 128x64 upsampled to 299 by torchmetrics; small n, treat as indicative only
Track D - single-image 3D Gaussians (Apple SHARP) rendered at the true next pose
10 CAM_FRONT keyframes (one per scene); Gaussians predicted from frame t, rendered at the identity pose and at the true relative pose of the next frame (nuScenes ego pose + calibration). Metrics only on pixels the render covers. GPU: NVIDIA L4.
| target | PSNR [95% CI] | SSIM | LPIPS (alex) | coverage | camera motion [m] |
|---|---|---|---|---|---|
| identity | 41.62 [40.69, 42.52] | 0.991 [0.987, 0.995] | 0.017 [0.014, 0.020] | 1.00 | 0.00 |
| next_sweep | 26.80 [24.70, 28.87] | 0.773 [0.683, 0.858] | 0.096 [0.071, 0.122] | 1.00 | 0.48 |
| next_keyframe | 20.42 [18.71, 22.09] | 0.592 [0.501, 0.684] | 0.231 [0.179, 0.290] | 1.00 | 2.82 |
Prediction time 5496 ms per image, render 22.0 ms per view (NVIDIA L4).